
EECE 421 Exam, Fall 2010
American University of Beirut · Computer Architecture · 5 pages



More EECE 421 files
Show the text of this exam
PROF. AKKARY
DEPT. OF ELECTRICAL AND COMPUTER ENGINEERING
January 3, 2011
AMERICAN UNIVERSITY OF BEIRUT
EECE 421 – COMPUTER Architecture
Quiz 3 – Fall 2010
NAME: __________________________________________
ID: ___________________________
INSTRUCTIONS:
(1)
Page 1 of 5
THE DURATION OF THE EXAM IS TWO HOURS. NO TIME EXTENSION.
THE EXAM IS CLOSED-BOOK/CLOSED-NOTES.
USING CELL PHONES IS NOT ALLOWED IN THE EXAMINATION ROOM.
WRITE YOUR NAME AND ID. NUMBER IN THE SPACE PROVIDED ABOVE.
CIRCLE ONLY ONE ANSWER.
READ THE QUESTIONS CAREFULLY BEFORE ANSWERING.
IN SOME QUESTIONS, MORE THAN ONE CHOICE MAY BE A VALID ANSWER. CIRCLE THE BEST CHOICE
YOU THINK IS THE MOST APPROPRIATE ANSWER TO THE QUESTION.
ALL QUESTIONS ARE EQUALLY WEIGHTED.
THERE IS NO PENALTY FOR WRONG ANSWERS.
USE THE BACK PAGES FOR SCRATCH IF NEEDED
CHECK THAT YOU HAVE A TOTAL OF 5 PAGES.
NO QUESTIONS ARE ALLOWED.
YOU CANNOT LEAVE THE EXAM ROOM FOR ANY REASON UNTIL YOU COMPLETE THE EXAM.
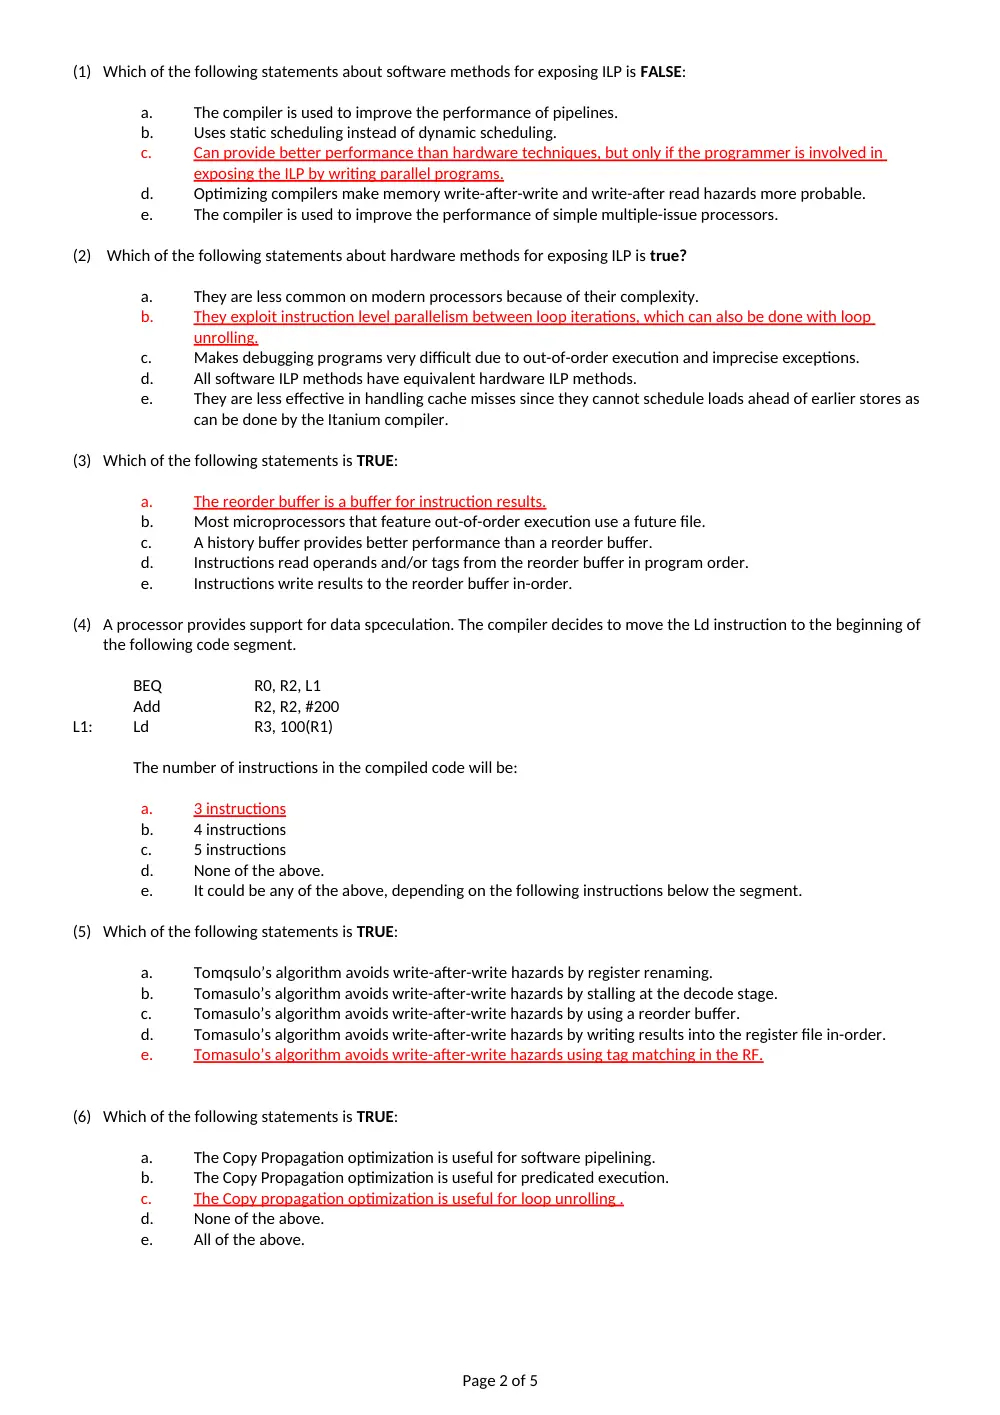
(1) Which of the following statements about software methods for exposing ILP is FALSE:
a.
The compiler is used to improve the performance of pipelines.
b.
Uses static scheduling instead of dynamic scheduling.
c.
Can provide better performance than hardware techniques, but only if the programmer is involved in
exposing the ILP by writing parallel programs.
d.
Optimizing compilers make memory write-after-write and write-after read hazards more probable.
e.
The compiler is used to improve the performance of simple multiple-issue processors.
(2) Which of the following statements about hardware methods for exposing ILP is true?
a.
They are less common on modern processors because of their complexity.
b.
They exploit instruction level parallelism between loop iterations, which can also be done with loop
unrolling.
c.
Makes debugging programs very difficult due to out-of-order execution and imprecise exceptions.
d.
All software ILP methods have equivalent hardware ILP methods.
e.
They are less effective in handling cache misses since they cannot schedule loads ahead of earlier stores as
can be done by the Itanium compiler.
(3) Which of the following statements is TRUE:
a.
The reorder buffer is a buffer for instruction results.
b.
Most microprocessors that feature out-of-order execution use a future file.
c.
A history buffer provides better performance than a reorder buffer.
d.
Instructions read operands and/or tags from the reorder buffer in program order.
e.
Instructions write results to the reorder buffer in-order.
(4) A processor provides support for data spceculation. The compiler decides to move the Ld instruction to the beginning of
the following code segment.
BEQ
R0, R2, L1
Add
R2, R2, #200
L1:
Ld
R3, 100(R1)
The number of instructions in the compiled code will be:
a.
3 instructions
b.
4 instructions
c.
5 instructions
d.
None of the above.
e.
It could be any of the above, depending on the following instructions below the segment.
(5) Which of the following statements is TRUE:
a.
Tomqsulo’s algorithm avoids write-after-write hazards by register renaming.
b.
Tomasulo’s algorithm avoids write-after-write hazards by stalling at the decode stage.
c.
Tomasulo’s algorithm avoids write-after-write hazards by using a reorder buffer.
d.
Tomasulo’s algorithm avoids write-after-write hazards by writing results into the register file in-order.
e.
Tomasulo’s algorithm avoids write-after-write hazards using tag matching in the RF.
(6) Which of the following statements is TRUE:
a.
The Copy Propagation optimization is useful for software pipelining.
b.
The Copy Propagation optimization is useful for predicated execution.
c.
The Copy propagation optimization is useful for loop unrolling .
d.
None of the above.
e.
All of the above.
Page 2 of 5
(7) Choose the one FALSE statement about recurrence software optimization.
a.
It may be useful when the value of an expression in one loop iteration is a function of a previous iteration.
b.
It is useful only for expressions that perform a sum function.
c.
It is useful only when performing loop unrolling.
d.
It is useful only with processors that can perform multiple operations in the same cycle.
e.
It is not useful for software pipelining.
(8) Which of the following is TRUE?
a.
The most significant factor in the performance of a VLIW processor is its compiler.
b.
NOPs are needed in VLIW programs only if its compiler uses global scheduling.
c.
NOPs impact VLIW processor power but not performance.
d.
All of the above are true.
(9) The main benefit of loop unrolling is to reduce loop overhead.
a.
True
b.
False
(10) The degree of loop unrolling by a compiler is limited by the code size increase and the instruction cache capacity, but not
by registers.
a.
True
b.
False
(11) Loop unrolling without static scheduling reduces performance due to code size increase.
a.
True
b.
False
(12) VLIW and Itanium architectures differ in how they access register operands, but not memory operands.
a.
True
b.
False
(13) Choose the most accurate statement:
a.
There is one main reason for code size increase in VLIW processors.
b.
There are 2 main reasons for code size increase in VLIW processors.
c.
There are 3 main reasons for code size increase in VLIW processors.
d.
Code size increase in VLIW processors occurs only if a trace scheduling compiler is used.
(14) Which of the following statements is TRUE:
a.
VLIW processor hardware does not check for dependences between instructions.
b.
VLIW processor hardware does not perform branch prediction.
c.
VLIW processor hardware does not check for exceptions.
d.
None of the above is true.
Page 3 of 5
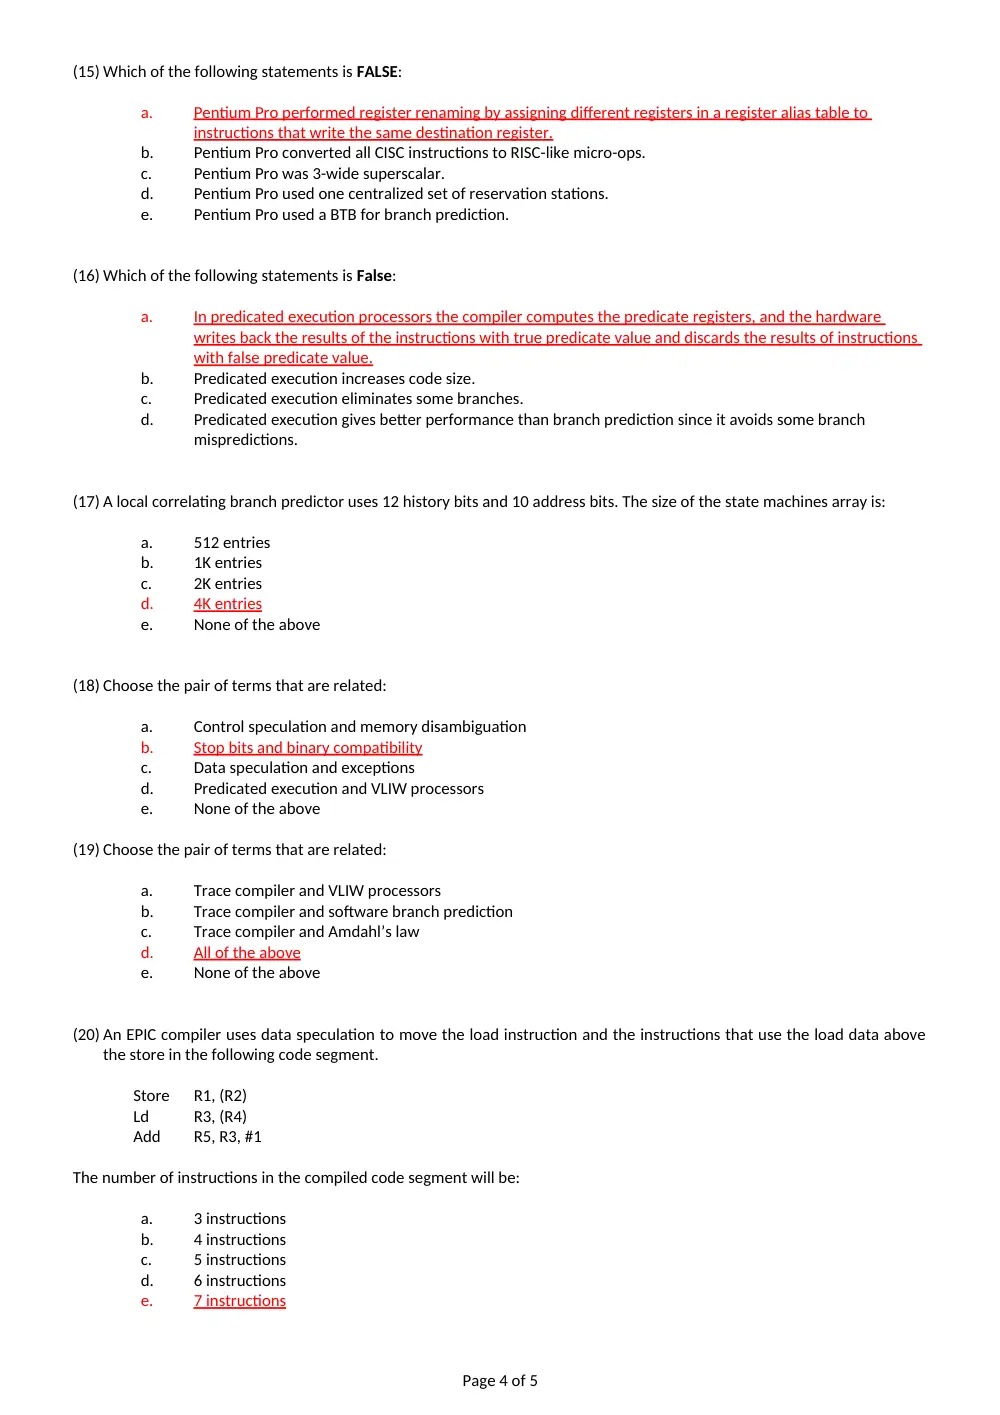
(15) Which of the following statements is FALSE:
a.
Pentium Pro performed register renaming by assigning different registers in a register alias table to
instructions that write the same destination register.
b.
Pentium Pro converted all CISC instructions to RISC-like micro-ops.
c.
Pentium Pro was 3-wide superscalar.
d.
Pentium Pro used one centralized set of reservation stations.
e.
Pentium Pro used a BTB for branch prediction.
(16) Which of the following statements is False:
a.
In predicated execution processors the compiler computes the predicate registers, and the hardware
writes back the results of the instructions with true predicate value and discards the results of instructions
with false predicate value.
b.
Predicated execution increases code size.
c.
Predicated execution eliminates some branches.
d.
Predicated execution gives better performance than branch prediction since it avoids some branch
mispredictions.
(17) A local correlating branch predictor uses 12 history bits and 10 address bits. The size of the state machines array is:
a.
512 entries
b.
1K entries
c.
2K entries
d.
4K entries
e.
None of the above
(18) Choose the pair of terms that are related:
a.
Control speculation and memory disambiguation
b.
Stop bits and binary compatibility
c.
Data speculation and exceptions
d.
Predicated execution and VLIW processors
e.
None of the above
(19) Choose the pair of terms that are related:
a.
Trace compiler and VLIW processors
b.
Trace compiler and software branch prediction
c.
Trace compiler and Amdahl’s law
d.
All of the above
e.
None of the above
(20) An EPIC compiler uses data speculation to move the load instruction and the instructions that use the load data above
the store in the following code segment.
Store
R1, (R2)
Ld
R3, (R4)
Add
R5, R3, #1
The number of instructions in the compiled code segment will be:
a.
3 instructions
b.
4 instructions
c.
5 instructions
d.
6 instructions
e.
7 instructions
Page 4 of 5
(21) A compiler can safely reorder the following instruction sequence.
BEQ
R1, R0, Label
Ld
R2, 100(R1)
a.
True
b.
False
(22) EPIC architecture does not provide precise exception state since loads that are moved ahead of branches could cause
exceptions.
a.
True
b.
False
(23) VLIW consumes less power than superscalars because it uses less complex hardware, therefore less logic gates.
a.
True
b.
False
(24) Software pipelining does not help performance of superscalar and VLIW architectures.
a.
True
b.
False
(25) A Software pipelining may not help performance of superscalar and VLIW architectures as much as loop unrolling.
a.
True
b.
False
Page 5 of 5