
CSI 312 Final, Fall 2010
American University of Science and Technology · Computer Architecture · 6 pages

More CSI 312 files
Show the text of this final exam
Question #2 (25 points):
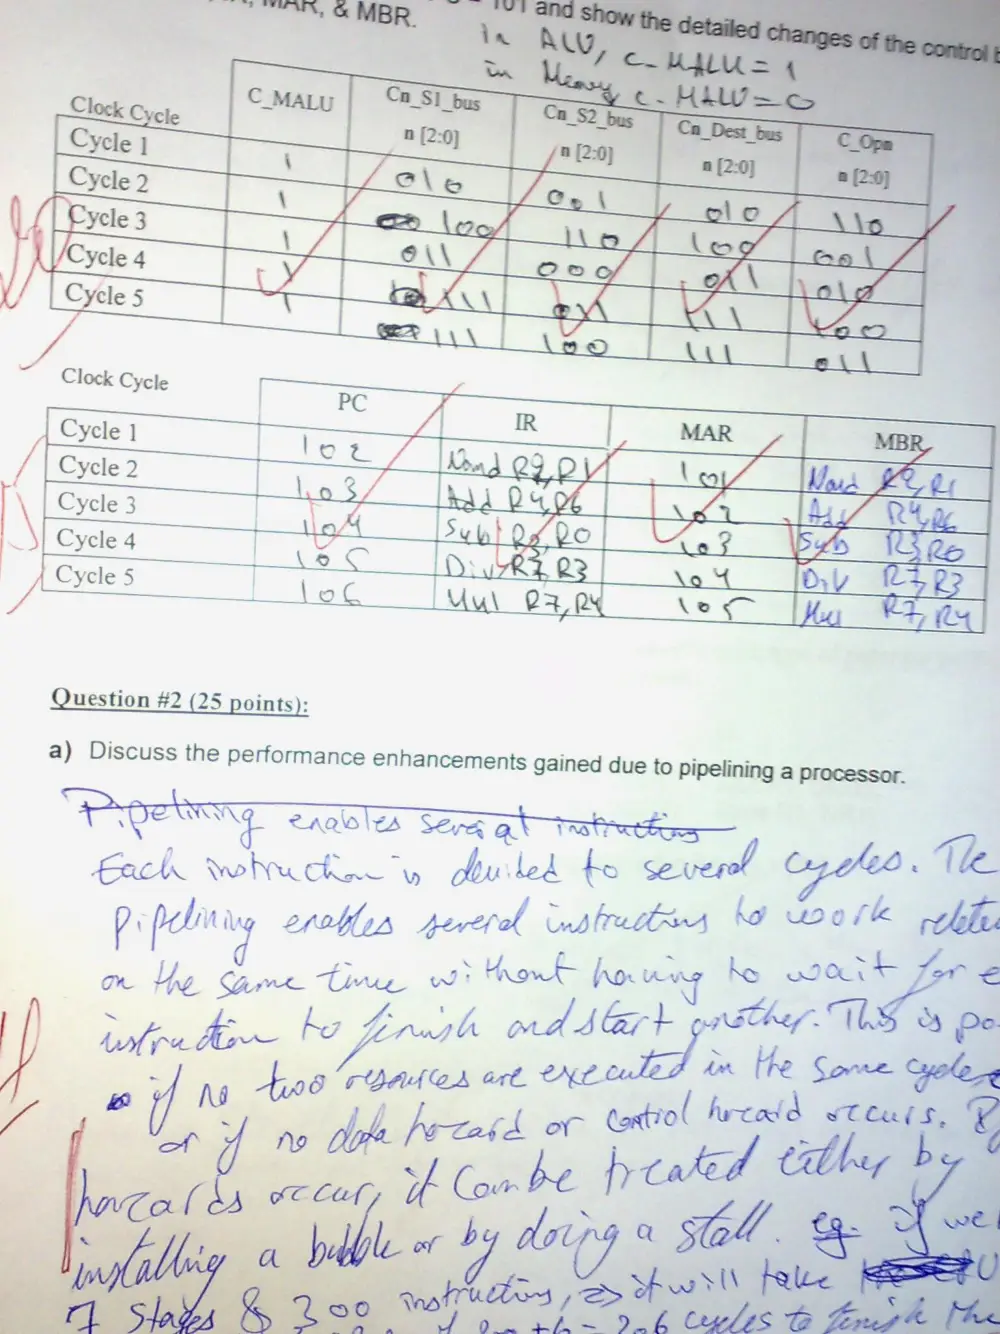
a) Discuss the performance enhancements gained due to Pipelining a processor.
+ peta eagles Sera Qt matrattins
Bach whucka vy dhurted fo severol ree The
Pipelining erobles penerol insfraatins bo a ele
om he Lu. Oe Howe houng be wor €
Hl) iifva din be Zrush ond dart gasther. WS % Be
ic aaa i in He Some Colon
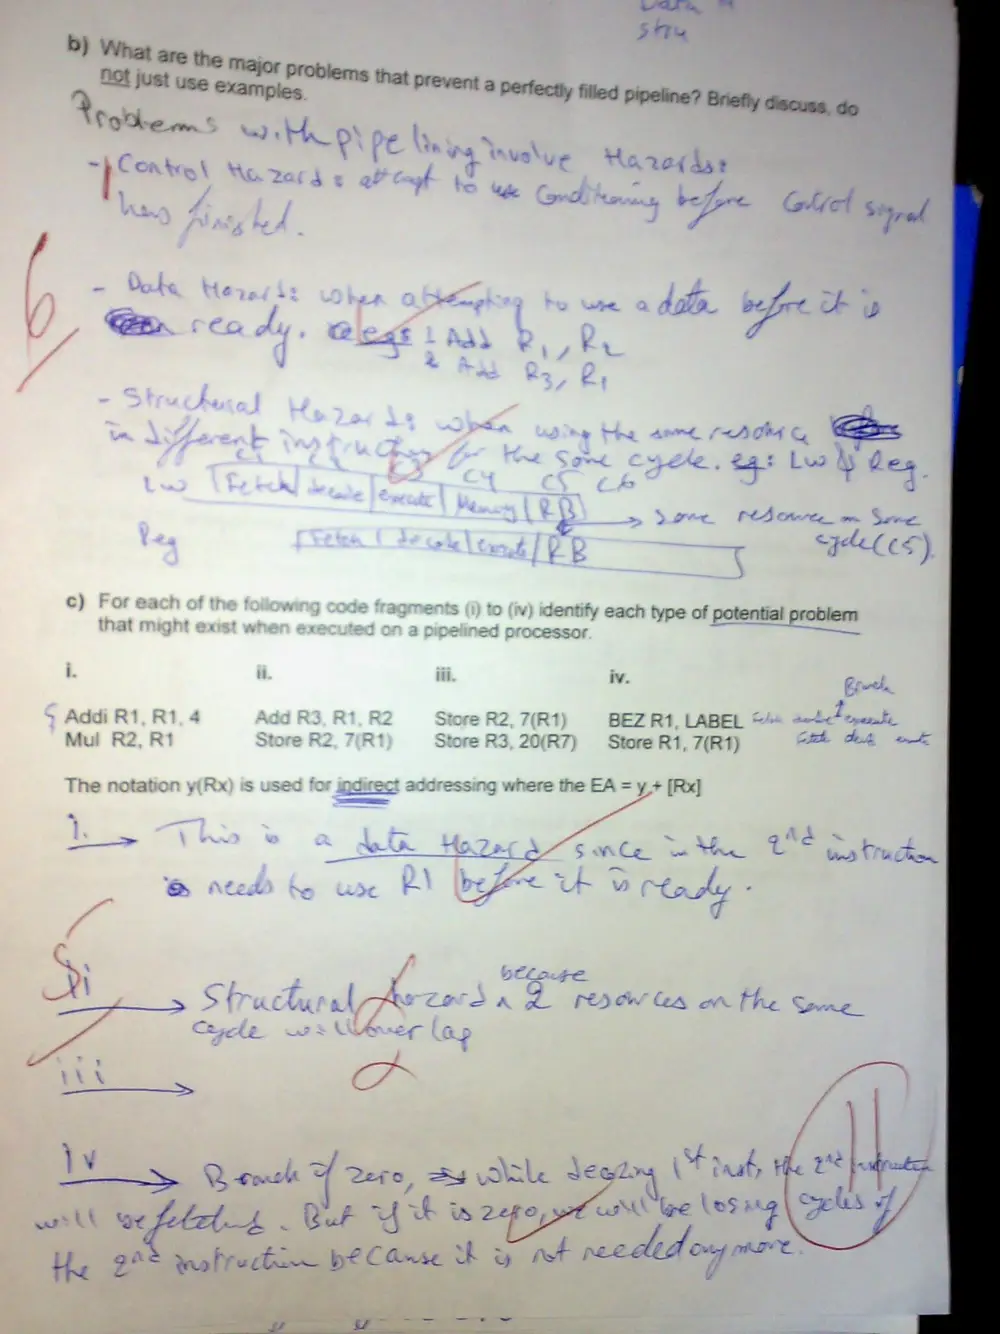
Ue Wes nM db Pecos or Coatio! hreadd Nie
all Wed of. Con be pycated Clbey
a
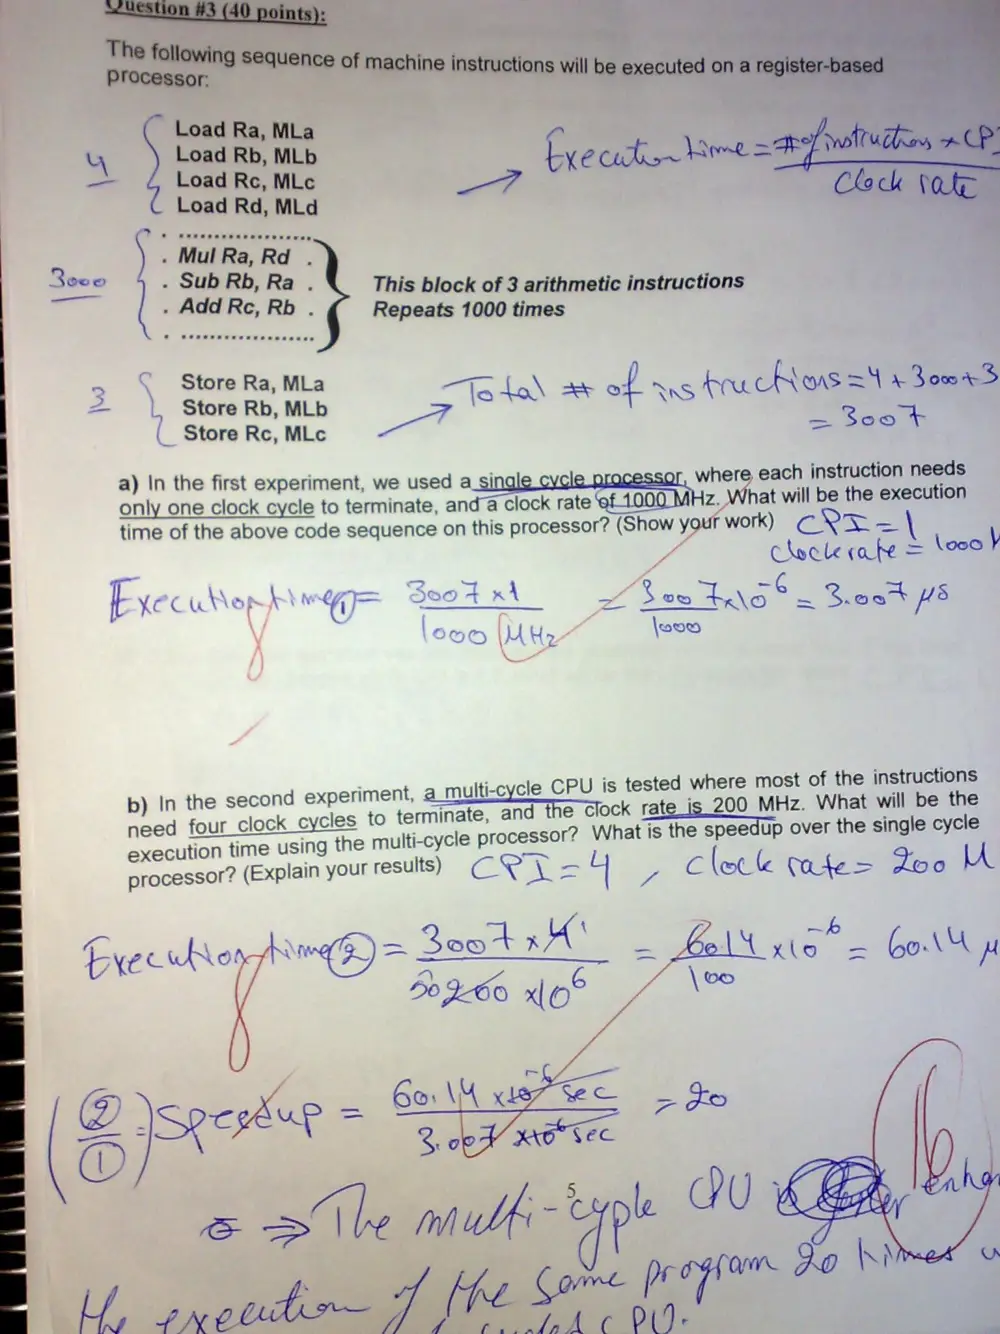
wamcstion #3 (40 points):
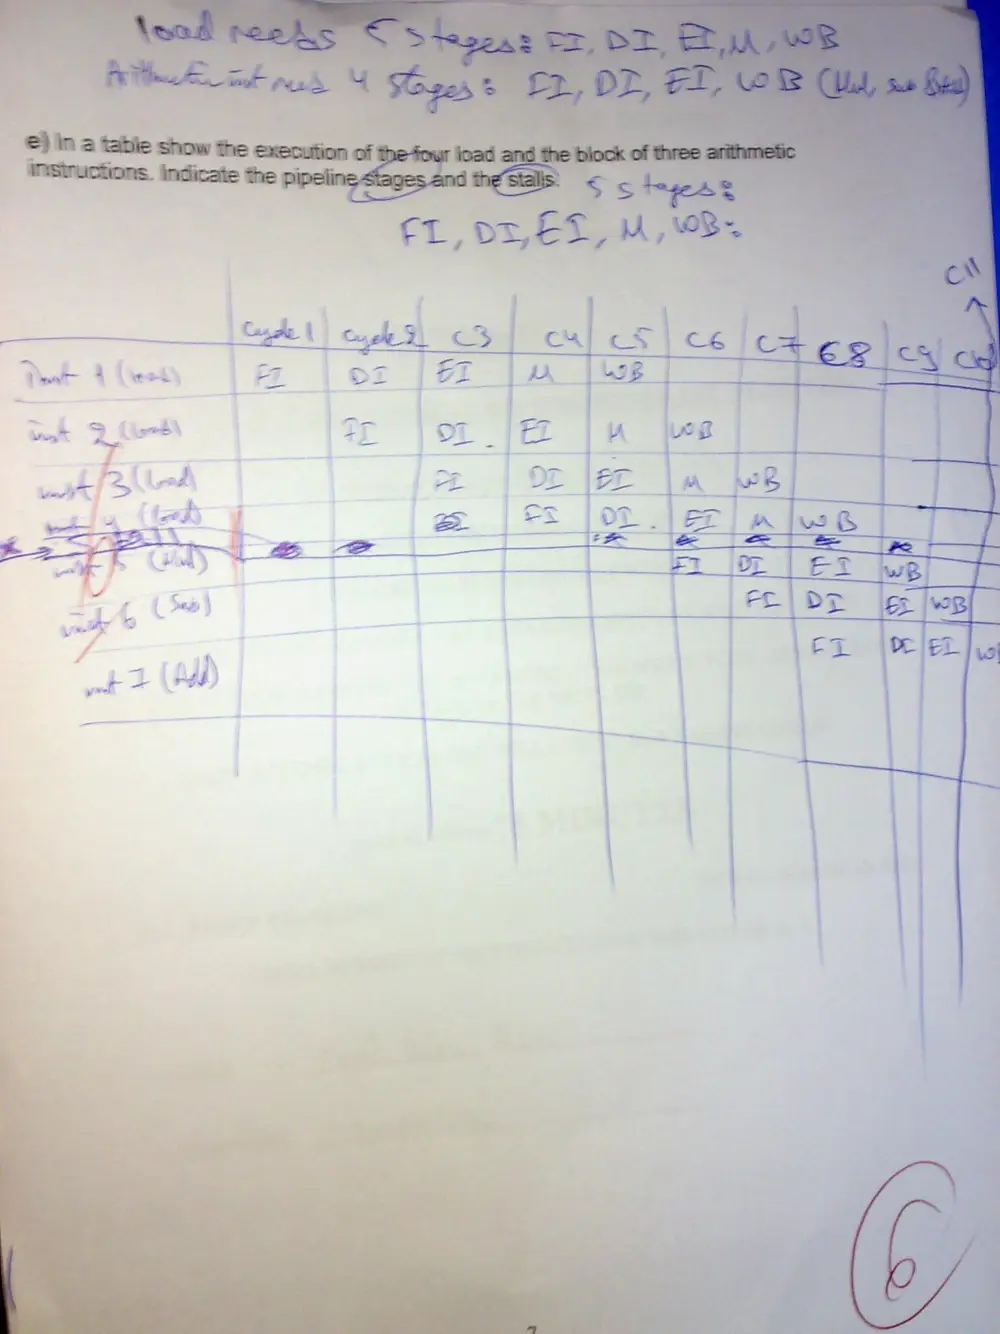
bichon Sequence of machine instructions will be executed on a register
Load Ra, MLa o Lame =F A htutiroy OP
Load Rb, MLb Xe cL pe ae.
* 4
a Load Re, MLce oe Clock hate
Load Rd, MLd
. Mul Ra, Rd
Beco - Sub Rb, Ra . This block of 3 arithmetic instructions
wee . Add Re, Rb . Repeats 1000 times
) —
> Store Ra, MLa an WEN es of Ans Aru cAons =4 430043
= |, Store Rb, MLb , Cae eta
(_ Store Rc, MLc
here each instruction needs
a) In the first experiment, we used bere ro \ the execition
only one clock cycle to terminate, anda clock rate 'z. What will be the
i ) CHES \
im ib de sequence on this processor? (Show your work)
time of the above co q| a : \
Frecut\op mage Ssctnt Bee tayo” = Seat H8
206 |U Hr \vow
i ted where most of the instructions
ment, a multi-cycle CPU is tes
b) In the second experi
lock cycles to ter in: if is 200 MHz. What will be the
need four c! y' minate, and the clock at 2 ;
nt - e =e ee: cle processor? What is the speedup over the single cycle
execution ti |
processor? (Explain your results) Clea 4 Clock bate = Dee UC
Soot K. - Zalit as* e
4)
20 FOO xo° se
EyecuWvror Ki we) =>
J \wo
|| | ktale